
Grok 4.7 is API only. There are no local weights. This brief covers the release, independent lab scores, and how to call the closed API. The list price is unchanged from Grok 4.6. Cost per task is higher.
Abstract Bitwidth cover. No xAI, Grok, SpaceX or Cursor logos.
What's new
Grok 4.7 shipped on September 21, 2026. The API slug is grok-4.7. Context is 500k tokens. Input is text and image. Output is text. Reasoning effort is low, medium, high, xhigh. Knowledge cutoff is May 2026.1
xAI says the base is larger than 4.6. No official parameter count is published. Training added longer RL on hard and long horizon tasks. Self verification improved. The model understands the Grok Bot harness natively. A new safeguard stack was added. Pricing is unchanged.1
It runs on xAI API Responses and Chat Completions. A US regional endpoint is available. Cursor supports it on all plans. Grok Build uses it as default. GitHub Copilot is rolling it out on Pro through Enterprise as of September 21. OpenRouter, Vercel and Cloudflare also list it.2^3
A Fast variant exists. It is 2x output speed at 2x price. It is available on Cursor and Grok Build only. It is not on the public API. It is not in the Grok Build free tier.2
Grok 4.8 was mentioned in training around September 22. No docs page exists. 4.8 is not shipped.
Safeguards are vendor reported only. HackerBench v0.3 shows 3.3% dual use through. LatchBio shows 62.4%. No independent reproduction exists as of 2026-09-23.1
Performance
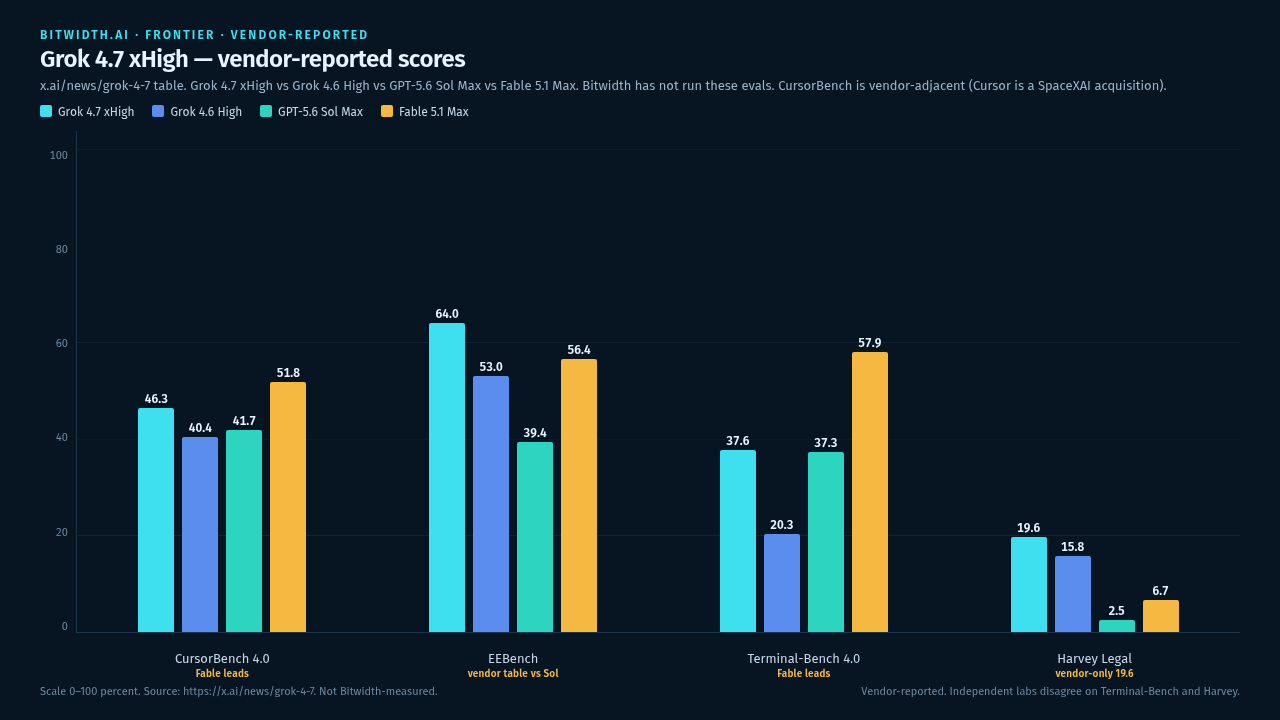
Vendor reported from https://x.ai/news/grok-4-7. Grok 4.7 xHigh vs Grok 4.6 High vs GPT-5.6 Sol Max vs Fable 5.1 Max. CursorBench 4.0 46.3 / 40.4 / 41.7 / 51.8. Fable leads. Cursor is vendor adjacent. EEBench 64.0 / 53.0 / 39.4 / 56.4. Terminal-Bench 4.0 37.6 / 20.3 / 37.3 / 57.9. Fable leads. Harvey Legal 19.6 / 15.8 / 2.5 / 6.7. Vendor only. Bitwidth has not run these evals. Independent labs disagree on Terminal-Bench and Harvey.
Vendor table from x.ai/news/grok-4-7. Grok 4.7 xHigh versus Grok 4.6 High versus GPT-5.6 Sol Max versus Fable 5.1 Max.
CursorBench 4.0: 46.3% / 40.4% / 41.7% / 51.8%. Cursor is SpaceXAI acquisition. Vendor adjacent. DeepSWE v1.1: 71.0%* / 65.2% / 72.7% / 70.0%. Star is high effort. EEBench: 64.0% / 53.0% / 39.4% / 56.4%. AA-Briefcase v1.1: 1,657 / 1,546 / 1,487 / 1,678. Terminal-Bench 4.0: 37.6% / 20.3% / 37.3% / 57.9%. Harvey Legal Agent Benchmark: 19.6% / 15.8% / 2.5% / 6.7%. HealthBench Professional: 56.7% / 48.5% / 60.5% / 62.1%. GDPval Elo: Fable 1735, 4.7 1695, 4.6 1605, GPT-6 Astra 1542.1
Independent composite. Artificial Analysis Intelligence Index v4.3.2 at xhigh is 46. Grok 4.6 high was 44. Fable 5.1 and GPT-6 Astra are 53. Opus 5.5 hit 58 the next day. Coding Agent Index with Grok Build is 56. That is 4th place and +9 versus 4.6.4
Terminal Bench 4.0 is a range not a point. Vendor is 37.6%. AA standardized harness is about 26%. AA plus Grok Build is 33%. Vals is 28.28% ± 1.34. Independent labs still have 4.7 in the mid 20s to low 30s. It trails Astra and Fable.4^5
Knowledge work Elo is the independent win. AA Briefcase is 1657. That is +111 versus 4.6. GDPval AA is 1695. That is +90. It sits just behind Fable.4
List price versus cost per task. List is $2 per million input and $6 per million output. AA cost per task is $3.74 xhigh and $2.73 high. GPT-5.6 Sol Max is about $1.99. Verbosity tax is real. About 81k output tokens per Intelligence Index task.4
LiveBench 2026-06-25 is independent. Grok 4.7 xHigh overall is 77.4. Grok 4.6 is 78.0. Cost per successful task is $0.718 versus $0.207. That is about 3.5x more.6
EEBench public board is independent. Grok 4.7 is 64.0% ± 9.6 rank 2. GPT-6 Astra leads at 69.3%. Astra cost per task is $0.83. Grok cost per task is $3.55. xAI compared against Sol 39.4% not the actual leader.7
Harvey. Vendor claims 19.6%. Vals independent is 12.50% ± 2.42. Independent labs do not confirm 19.6%.5
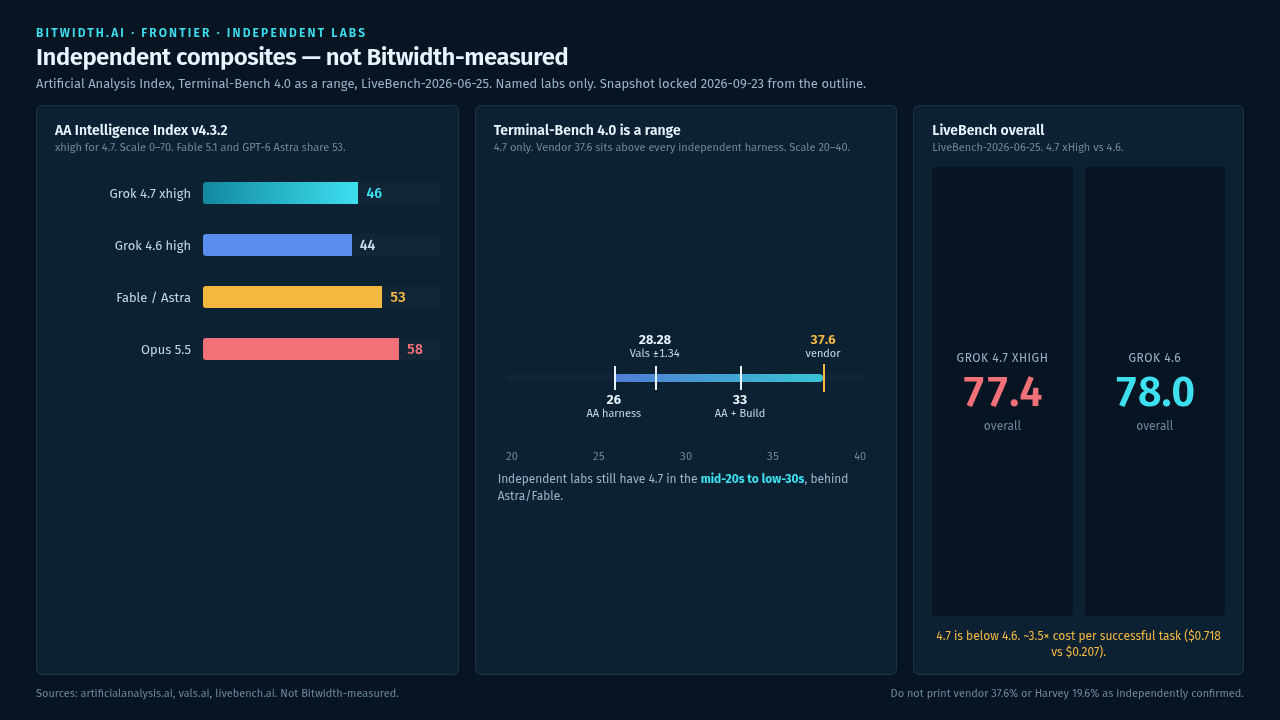
Independent labs, not Bitwidth. AA Intelligence Index v4.3.2: 46 for 4.7 xhigh vs 44 for 4.6 high vs 53 for Fable 5.1 and GPT-6 Astra vs 58 for Opus 5.5. Terminal-Bench 4.0 for 4.7 is a range: vendor 37.6, AA standardized harness ~26, AA plus Grok Build 33, Vals 28.28 ± 1.34. LiveBench 2026-06-25 overall: 4.7 xHigh 77.4 is below Grok 4.6 78.0, at ~3.5x cost per successful task. Do not treat vendor 37.6% or Harvey 19.6% as independently confirmed.
Local setup
Grok 4.7 is API only. No local weights exist. No Hugging Face card. No GGUF. No Unsloth. No llama.cpp. No vLLM checkpoint. Grok-1 and Grok-2 weights exist. They are not 4.7.2
xAI API. Get a key from console.x.ai. Global host is https://api.x.ai/v1. Use Responses or Chat Completions. Slug is grok-4.7 with a dot. Set prompt_cache_key or x-grok-conv-id for cache hits. Encrypted reasoning is always on Responses.
curl https://api.x.ai/v1/responses \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $XAI_API_KEY" \
  -d '{
    "model": "grok-4.7",
    "input": "Find and fix the bug, then explain it: function median(a){a.sort();return a[a.length/2]}"
  }'
Python with xai-sdk or OpenAI SDK works. The model slug is grok-4.7.
US regional endpoint. Host is https://us.api.x.ai/v1. It adds 10% premium. It serves grok-4.7 and grok-4.6 only. grok-latest returns 404 here.8
Cursor, Grok Build, Copilot. Fast is Cursor and Grok Build only. Copilot SKUs are rolling out September 21.3
Pricing. Below 200k prompt tokens: $2 input, $0.50 cached, $6 output per million. At or above 200k: $4 input, $1 cached, $12 output. All tokens in the request bill at the long context rate. US is 1.1x. Fast is $4/$12 then $6/$18. No batch discount on 4.7.9
Rate limits. Tiers are by spend since 2026-01-01. Grok 4.7 T0 is 150 RPS and 50M TPM. T4 is 500 RPS and 100M TPM. Same caps as 4.5 and 4.6.10
Local runtime is not possible. One DGX Spark is not a fit. Two DGX Sparks are not a fit. RTX 5090 and below are not a fit. Phone and edge are not a fit. The box can still call the API.
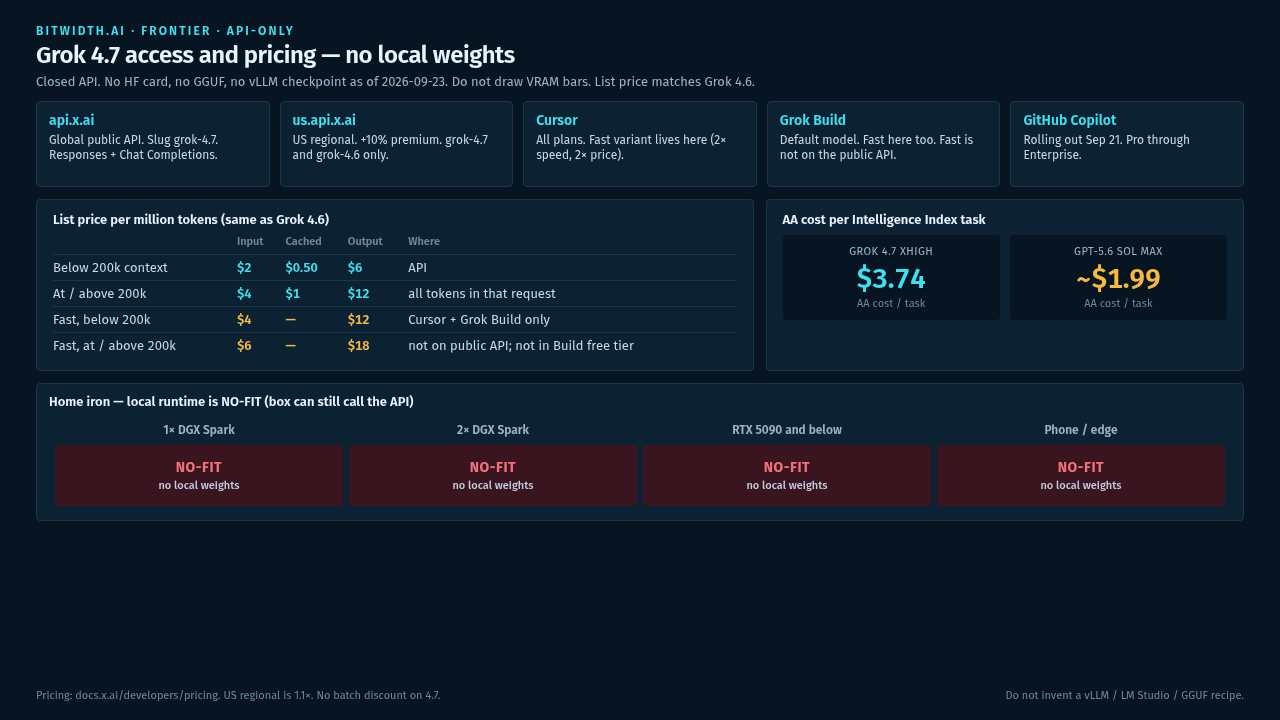
API only. Channels: api.x.ai, us.api.x.ai plus 10%, Cursor, Grok Build, GitHub Copilot. List price below 200k: $2 / $0.50 cached / $6. At or above 200k: $4 / $1 / $12. Fast is 2x price and Cursor/Grok Build only. AA cost per Intelligence Index task $3.74 xhigh vs ~$1.99 GPT-5.6 Sol Max. Local runtime NO-FIT on 1x Spark, 2x Spark, RTX 5090 and below, and phone/edge. No VRAM bars. No GGUF or vLLM recipe.


