NVIDIA's FP4-Local cut of Qwen3.8-Flash-Next is serving on one DGX Spark at a measured 1,048,576-token window. It runs from a digest-pinned b12x container. Upstream vLLM cannot load the checkpoint.
What's new
NVIDIA released nvidia/Qwen3.8-Flash-Next-FP4-Local on Hugging Face on 2026-10-05. The checkpoint is about 96 GB on disk. The lab used snapshot b9ce18a6887e18c089fdea8509a33e63429a3300. The model card is at Hugging Face 1. The lab download was 33 files. It took about 15 minutes. The Spark was already logged in to Hugging Face.
The base is Qwen3.8-Flash-Next from Alibaba Qwen Team. Release date is 2026-08-26. Architecture preview is qwen4_exp. It uses hybrid attention. Gated DeltaNet is on three of four layers. Qwen Sparse Attention is on the fourth. It is a Mixture of Experts. Total is about 125B. Active is about 6B. It has a 51B n-gram PLE embedding table. It has a 4B MTP head. Vision encoder is present.
Quantization is NVFP4 via Quantization Aware Distillation. NVIDIA Model Optimizer v0.47.0 is used 4. Routed experts are QAD NVFP4. Attention is MXFP8 FP8. PLE table is FP8. MTP head is BF16.
License is NVIDIA Open Model Agreement 2. It governs download terms. Qwen Community License 1.0 applies to the base model 3. Commercial and non commercial use is permitted.
Upstream vLLM cannot load this checkpoint. NVFP4 expert scales use a new lossless compression format. The model card says you must use a provided container. vllm/vllm-openai:latest cannot load nvidia/Qwen3.8-Flash-Next-FP4-Local. The working server is a digest-pinned community image 10.
Native context is 262,144. YaRN factor 4 extends it. 262144 times 4 equals 1,048,576. That is the window left running in the lab.
One Spark is enough. A second Spark was not used.
Performance
NVIDIA reported these scores. This lab did not re-run them.
NVIDIA reported for FP4-Local GPQA Diamond 91.5 percent. ToolEvalBench is 88.7 percent 1. BF16 baseline for Qwen3.8-Flash-Next is GPQA Diamond 92.2 percent. ToolEvalBench is 89.4 percent. Delta is minus 0.7 percentage points on both.
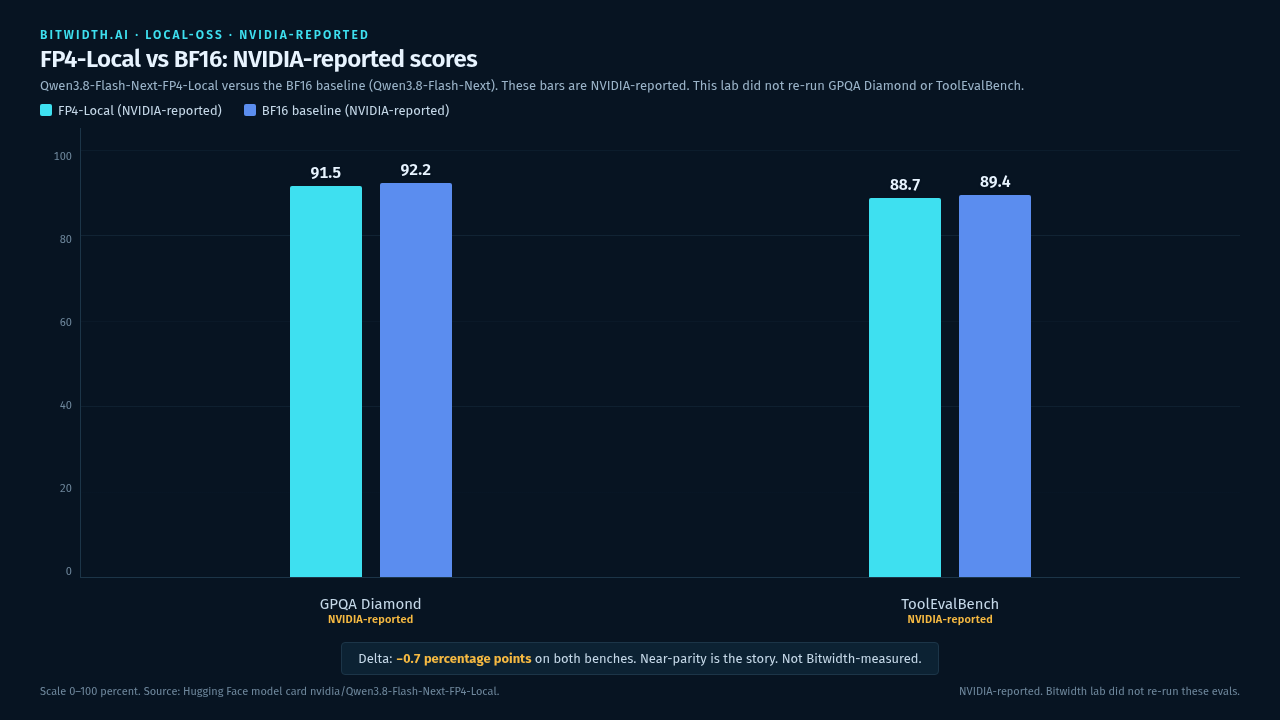
NVIDIA-reported scores, not this lab.
Bitwidth lab, one DGX Spark, 2026-10-19.
Engine log shows FP8 KV cache 1,612,385 tokens. Maximum concurrency at 1,048,576 is 1.54x. Weights are 71.19 GiB. About 12 GiB of 121 GiB remains for the OS after load. KV reservation is 23.5 GiB.
Card claim versus lab. NVIDIA card says 1M tokens of FP8 KV with PLE offload on a Spark. Lab allocation was 1,612,385 tokens at max_model_len 1,048,576.
Short completion thinking-off pong in 0.31 s. Finish reason is stop.
Short decode is 112 completion tokens in 3.33 s wall. That is about 34 tok/s. Thinking is off. Client wall clock includes prefill. One short prompt was used. This is not a concurrency sweep.
40,046 token needle exact code returned in 16.2 s.
300,046 token needle exact code 7F-Qwen-Spark-19 returned in 131.5 s. This is past the native 262,144 window.
A full 1,048,576 token prompt was not run. The cache is large enough for one request of that length. The long test actually run is 300,046 tokens.
Bring up is about 5 minutes once weights are on disk. First boot is about 8 minutes.
N-gram table is about 26 GB. It is paged from disk. VLLM_PLE_TABLE_MEMORY=disk is set. B12X_DISK_BACKEND=io_uring is set. That leaves room for the KV cache.
MTP is configured with 4 speculative tokens. Log said no KV cache group was identified as the draft model. Acceptance rate was not measured.
Transformers warned that mrope_interleaved and mrope_section are unrecognized under rope_type yarn. The 300,046 token retrieval still matched.
Vision flags were left on with mm-encoder-tp-mode data. No image request was sent.
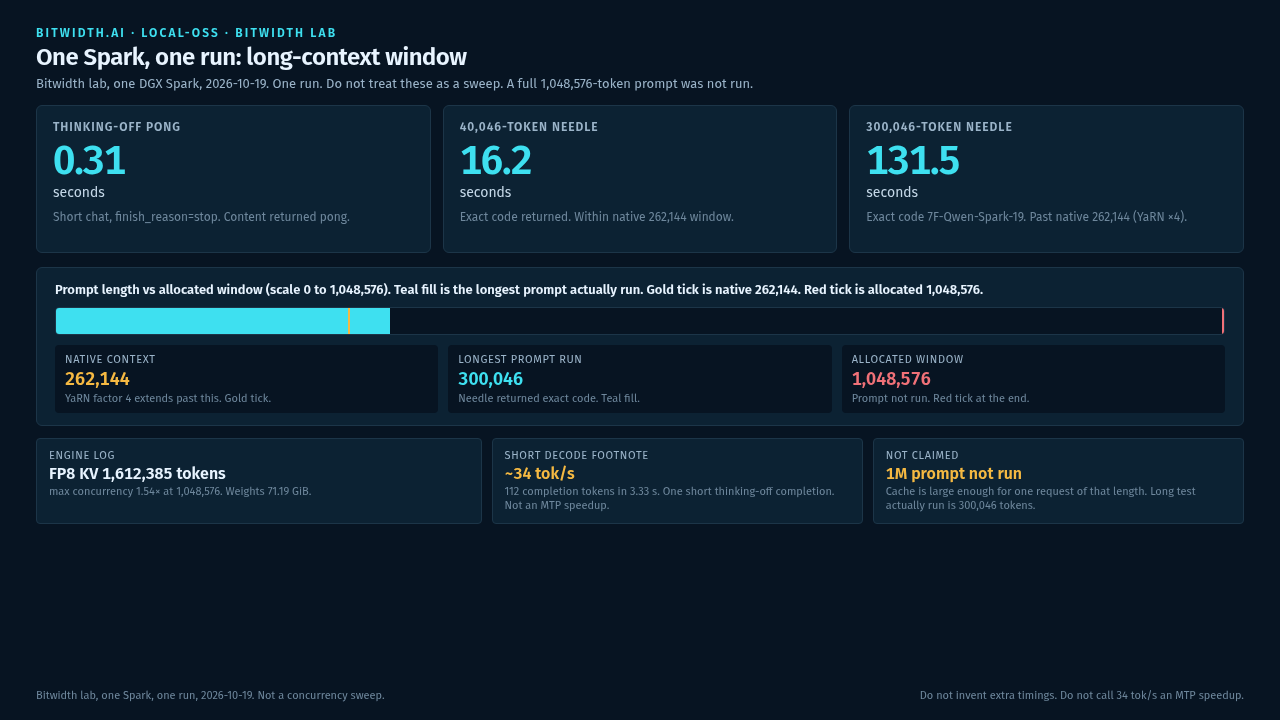
Bitwidth lab, one Spark, one run.
Independent community runs used different recipes. They are not this lab.
luisiam posted on NVIDIA forums. Recipe is official NVIDIA. One Spark. Image is eugr/spark-vllm-b12x:latest. Llama benchy shows 48.88 tok/s short. 32.86 tok/s at 32K. Tool eval bench is 100/100 short. 89/100 hard 6.
ai-muninn used tonyd2wild recipe. It uses stock nightly vLLM plus overlays. It is not the b12x pin this lab used. Median is 41.7 tok/s. Prose is 27.4. Aggregate at 4 streams is 47.2 7.
tsarihan tested 2x Spark TP=2. NVFP4 vs FP8. NVFP4 is 28 to 52 percent faster across concurrency 1 to 64 8. This lab did not run two Sparks.
CrucibleMark posted 81.02 total. Output is 41.18 tok/s. Coverage is 100 percent 9. That score is community. The checkpoint recipe may differ from this lab's pin.
Local setup
vLLM
vllm/vllm-openai:latest cannot load nvidia/Qwen3.8-Flash-Next-FP4-Local. The working server is the digest-pinned community image.
Download first:
hf download nvidia/Qwen3.8-Flash-Next-FP4-LocalThe lab pull was 33 files. It took about 15 minutes. Pin the image digest before docker run.
docker run --device nvidia.com/gpu=all \
  --ipc=host \
  --shm-size=16g \
  -v ~/.cache/huggingface:/root/.cache/huggingface \
  -p 8000:8000 \
  -e VLLM_PLE_TABLE_MEMORY=disk \
  -e B12X_DISK_BACKEND=io_uring \
  -e CUTE_DSL_ARCH=sm_121a \
  -e SAFETENSORS_FAST_GPU=1 \
  -e VLLM_WORKER_MULTIPROC_METHOD=spawn \
  -e VLLM_SSM_CONV_STATE_LAYOUT=DS \
  -e VLLM_USE_AOT_COMPILE=1 \
  -e VLLM_USE_MEGA_AOT_ARTIFACT=1 \
  -e VLLM_USE_V2_MODEL_RUNNER=1 \
  -e B12X_POLICY_MODE=auto \
  -e VLLM_MXFP8_LM_HEAD=1 \
  -e VLLM_B12X_MOE_FP4_LAYER_MAX_INPUT_SCALE=w13 \
  -e VLLM_B12X_MOE_FP4_FORCE_A16=1 \
  -e B12X_W4A16_A4_PREFILL=1 \
  -e B12X_COMPILE_WORKERS=1 \
  -e B12X_AUTOTUNE=0 \
  -e VLLM_ALLOW_LONG_MAX_MODEL_LEN=1 \
  eugr/spark-vllm-b12x:latest@sha256:03a956544e9f9b4b7ba91690469fbe7848bdbef29a7d2e0f5788368467bb3595 \
  nvidia/Qwen3.8-Flash-Next-FP4-Local \
  --host 0.0.0.0 --port 8000 \
  --tensor-parallel-size 1 --pipeline-parallel-size 1 \
  --mamba-cache-mode align \
  --enable-prefix-caching --enable-chunked-prefill \
  --dtype bfloat16 --kv-cache-dtype fp8 \
  --quantization modelopt_mixed --block-size 16 \
  --load-format b12x \
  --max-model-len 1048576 \
  --max-num-seqs 8 --max-num-batched-tokens 4096 \
  --gpu-memory-utilization 0.85 \
  --gdn-decode-kernel b12x --linear-backend b12x --moe-backend b12x \
  --no-enable-flashinfer-autotune \
  --mm-encoder-tp-mode data \
  --reasoning-parser qwen3 --tool-call-parser qwen3_xml --enable-auto-tool-choice \
  --compilation-config '{"pass_config":{"fuse_act_quant":true}}' \
  --hf-overrides '{"text_config":{"rope_parameters":{"mrope_interleaved":true,"mrope_section":[11,11,10],"rope_type":"yarn","rope_theta":10000000,"partial_rotary_factor":0.25,"factor":4.0,"original_max_position_embeddings":262144}}}' \
  --speculative-config '{"method":"mtp","num_speculative_tokens":4,"max_model_len":1048576}'
Ready check:
curl -s http://127.0.0.1:8000/v1/modelsShort thinking-off chat:
curl http://127.0.0.1:8000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{
    "model": "nvidia/Qwen3.8-Flash-Next-FP4-Local",
    "messages": [{"role": "user", "content": "ping"}],
    "chat_template_kwargs": {"enable_thinking": false},
    "max_tokens": 16
  }'
Thinking-off for a client is top-level JSON chat_template_kwargs.enable_thinking set to false. A short prompt with that field returned content pong. Zero reasoning tokens were produced.
B12X_AUTOTUNE=0 prevents hours of kernel autotune. B12X_COMPILE_WORKERS=1 avoids OOM on 128 GB Spark. VLLM_ALLOW_LONG_MAX_MODEL_LEN=1 is required above 262,144.
Community note. PLE weight_scale load failure on stock vLLM vllm#54765 5 is fixed in nightly 0.31.1rc1. It still fails on the old qwen38-flash-next tagged image. This guide's working path is the digest-pinned b12x container. It is not that tagged image.
LM Studio / llama.cpp
No official GGUF from NVIDIA for this FP4-Local checkpoint.
A community Strata split exists at hardhant/Qwen3.8-Flash-Next-FP4-Local-Strata. It includes mmproj, PLE, dense, token embd files. It is a split. It is not a single unified GGUF.
The working path for this checkpoint remains the b12x container.
One DGX Spark
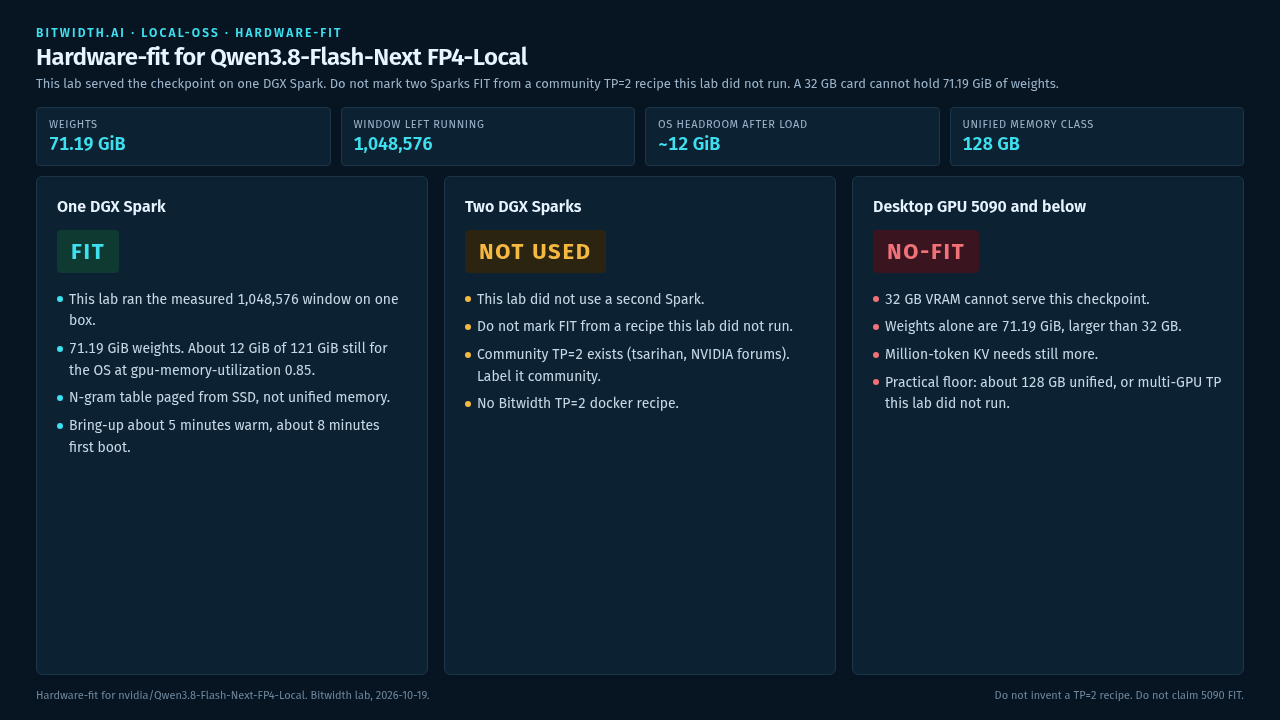
One Spark with GB10, 128 GB unified is enough. This lab ran the measured window on one box.
Weights are 71.19 GiB. After load about 12 GiB of 121 GiB remains for OS at gpu-memory-utilization 0.85.
N-gram table is paged from SSD. It is not in unified memory.
Use the docker run above with --device nvidia.com/gpu=all.
Bring up is about 5 minutes warm. First boot is about 8 minutes.
Two DGX Sparks
This lab did not use a second Spark.
Community. tsarihan published a 2x Spark TP=2 NVFP4 vs FP8 sweep on NVIDIA forums 8.
Desktop GPU (5090 and below)
32 GB card cannot serve this checkpoint. Weights alone are 71.19 GiB. That is larger than 32 GB VRAM. Million token KV needs still more.
Practical floor is about 128 GB unified memory DGX Spark class. Multi GPU tensor parallel is an option. This lab did not run it.